Guide
Build the Test Set Before You Choose the Tool, and Every AI Decision Rests on Your Own Evidence
A demonstration uses clean examples. We build a test set from your real cases first, so you hold a measured score on your own work before anything reaches production.
4-minute read3 November 2026
In Brief
- A demonstration is persuasive by design and seen once. It says little about the thousandth invoice, in the second year, after a supplier changes its template.
- We see four actions: collect real cases with known answers, define a correct outcome and the cost of an error, read the failures by hand, and run every later change against the same set.
- Thinqmesh builds the test set and a measured score on your own files in week one, then automates one job from start to finish, with a person checking anything that costs money.
An AI demonstration is persuasive by design. It uses clean examples, it is run by someone who knows the system, and it is seen once. None of that shows how the system will behave on the thousandth invoice, in the second year, after a supplier changes its template. Our view is that the first piece of work is a test set built from your own cases, and that it comes before the choice of tool.
A Test Set Turns a Claim Into a Figure You Can Check
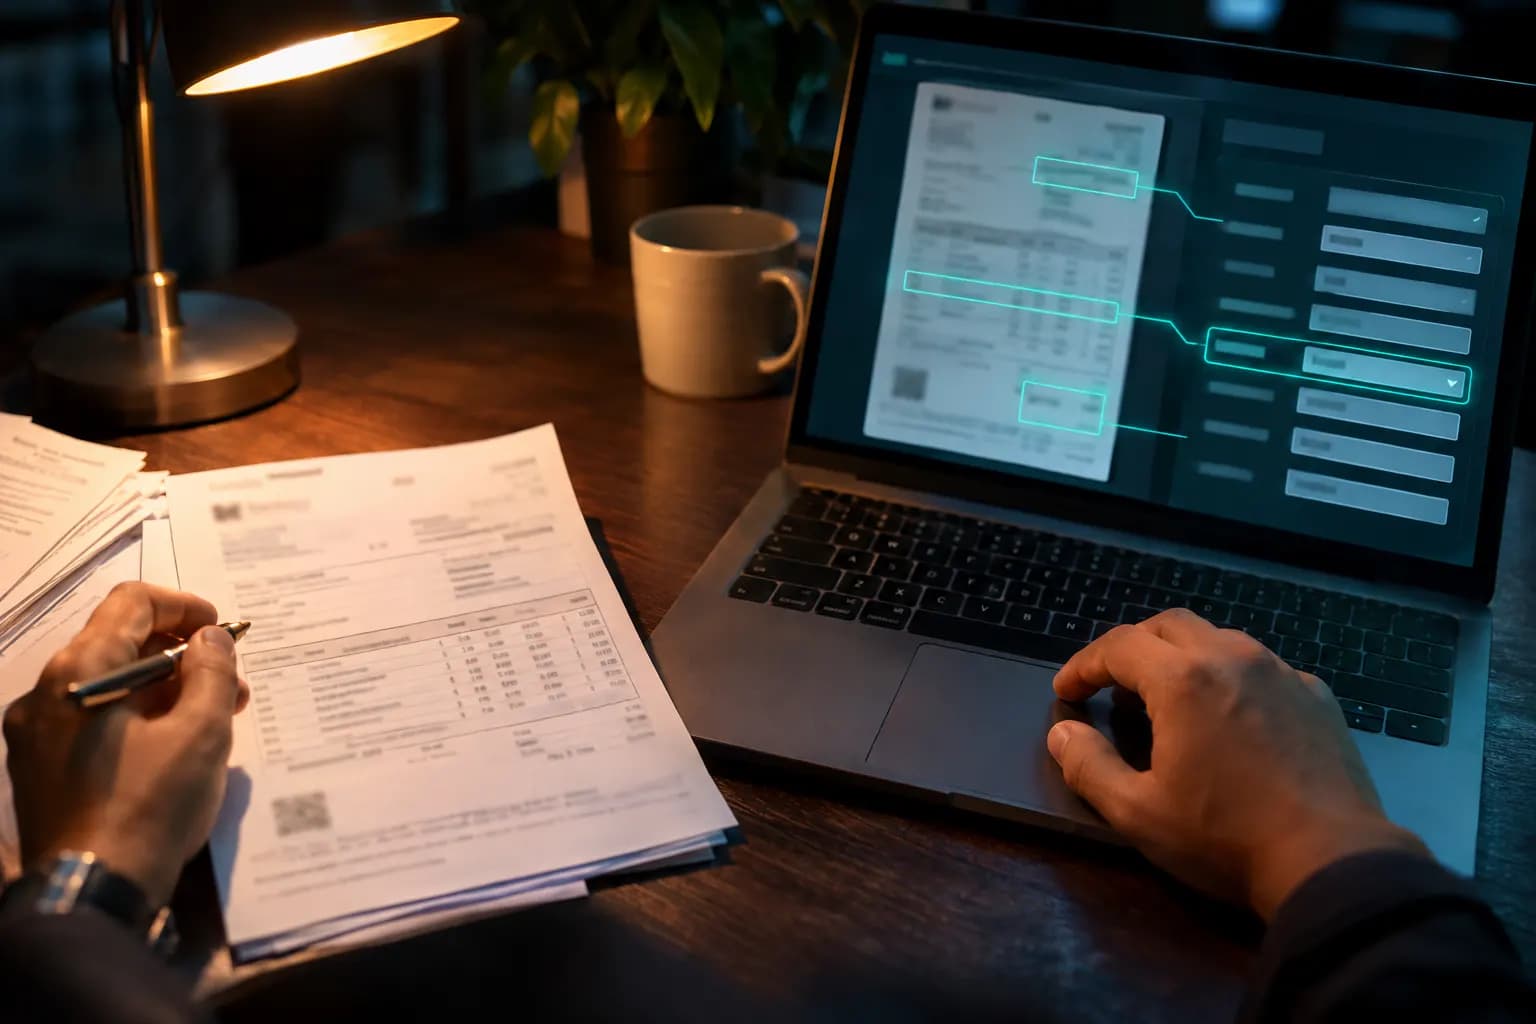
A test set is a collection of real cases from your operations where the correct answer is already known: several hundred invoices with the values a person extracted correctly, or the questions your team receives with answers your specialists approved. Running a system against it produces a score on your own work, and a list of exactly where the system is wrong.
Building it first tests your data, requires the business to define a correct outcome and the cost of an error, and makes risk something a leadership team can discuss. Kept in place, it becomes a permanent control, because every change runs against it before it reaches production.
Four Actions That Put Evidence Ahead of Enthusiasm
The first three need only your own people and your own cases, so you can begin before any tool is chosen.
Collect Real Cases Where the Answer Is Already Known
Several hundred invoices with the values a person extracted correctly, or the questions your team receives with answers your specialists approved.
These cases become the target. Assembling them quickly shows whether records are complete, consistent and accessible, so it tests your data as well. If the data is not ready, it is far cheaper to learn that in the first week than in the third month.
Get started
- Pick one job and pull fifty real cases with the correct answer beside each.
- Note any case where two people would give different answers.
Define a Correct Outcome and What an Error Costs
An initiative that cannot answer these questions is not yet ready for investment, whatever the technology can do.
To build the set, the business has to state what correct means and what a wrong answer costs. A statement such as the system is accurate cannot be governed. A statement such as it extracts totals correctly in this share of cases, fails in these situations, and a person reviews anything under a stated threshold can.
Get started
- Write what a correct result looks like for your chosen job.
- Estimate what one wrong result costs in time or money.
Read the Failures by Hand
The score matters, and the list of where the system is wrong matters more.
We read the results by hand before automating any judgement about them. The failures show whether a better prompt, better data, a conventional rule or a person is the right answer for each kind of case. Where the evidence favours conventional software, we recommend it in writing.
Get started
- Run any candidate tool on your fifty cases.
- Group the wrong answers by the reason they went wrong.
Run Every Change Against the Same Set
Models are updated, source documents change and the mix of cases drifts, all without any change to your own code.
Kept in place, the test set becomes a control. A change that would reduce accuracy fails before it reaches production, and live cases handled badly are added over time, so the set stays representative. Leadership holds a figure it can check for itself.
Get started
- Decide who owns the test set after launch.
- Agree the score below which a change may not go live.
How Thinqmesh Solves This
We begin with one job you bring us. Each initiative is tested on your own cases, where the correct answer is already known, before anything reaches production. A defined scope on an established platform takes four weeks.
- Week 1
Your Cases, Read by Hand
We look at your real cases and read the results by hand. By the end of the week you hold a test set and a measured accuracy score on your own files.
- Week 2
The Job, Built With Its Checks
The first job is built end to end on your own system, with the test set running against every change.
- Week 3
A Person on Anything Costly
A person reviews the work wherever a wrong answer costs money, and pending reviews are visible. Tax, statutory filings and payroll sums keep a human decision.
- Week 4
The Job Running, Watched
The job runs on your own system, with ongoing checks that keep accuracy in view and a way for your team's own AI tools to ask the system questions.
You finish with one job automated from start to finish, a test set built from your cases, a measured score with the mistakes named, and ongoing checks that keep accuracy in view.